The Circuitry
THE CIRCUITRYYour one-stop source for all tech news
HOMETODAYNEWSFEEDEVENTS
BOOKMARKS
RSS
© 2026 The Circuitry
About UsSourcesContactCorrectionsPrivacy
  • Today
  • Feed
  • Events
  • Saved
  • AAPL
  • MSFT
  • GOOGL
  • META
  • NVDA
  • TSLA
  • AMZN
  • INTC
  • SONY
  • TTWO
  • COIN
  • BTC
  • ETH
  • SOL
  • AAPL
  • MSFT
  • GOOGL
  • META
  • NVDA
  • TSLA
  • AMZN
  • INTC
  • SONY
  • TTWO
  • COIN
  • BTC
  • ETH
  • SOL

Feed

Ad
From The CircuitryVerified tech news, cross-checked.How we verify →
  • DeepSeek opens app tools on the API for V4.1-FlashTech
  • Starship Flight 15 deploys 26 Starlink satellites in orbitTech
  • OpenAI opens Daybreak Red Team and Defense FactoryTech
  • Uber says a vendor breach exposed driver license dataSecurity
  • OpenAI opens ChatGPT Wallet for U.S. Pro usersTech
  • FAA ground stop halts departures at U.S. airportsTech
  • Starship Flight 15 reaches orbit after a Gulf splashdownTech
  • Tesla opens Cybercab orders to select customers at $29,990Tech
Scroll for more
Verification
VERIFIEDConfidence: HIGH
Source identified
Claims cross-referenced
No discrepancies found
Sourcing
1source
Nvidia · track record
3Stories
100%Verified
330d
All sources →
Markets
NVDA···

Live quote · not investment advice

Ad
From The CircuitryWhy The Circuitry

Verified tech news, cross-checked.

Every story is checked against independent sources before it posts — no rumors dressed up as fact.

How we verify →
From The CircuitryWhy The Circuitry

Verified tech news, cross-checked.

Every story is checked against independent sources before it posts — no rumors dressed up as fact.

How we verify →
Home/Tech/Nvidia says Vera Rubin NVL72 delivers up to 30x GB300 throughput per dollar
VERIFIEDBy Xavier Rivera·Thursday, November 5, 2026 at 12:16 PM AST·2 min read

Nvidia says Vera Rubin NVL72 delivers up to 30x GB300 throughput per dollar

Nvidia said Vera Rubin NVL72 delivers up to 30x the throughput per dollar of GB300 NVL72 at 125 tokens per second per user, with HBM per GPU up about 3%. The post names no ship date.
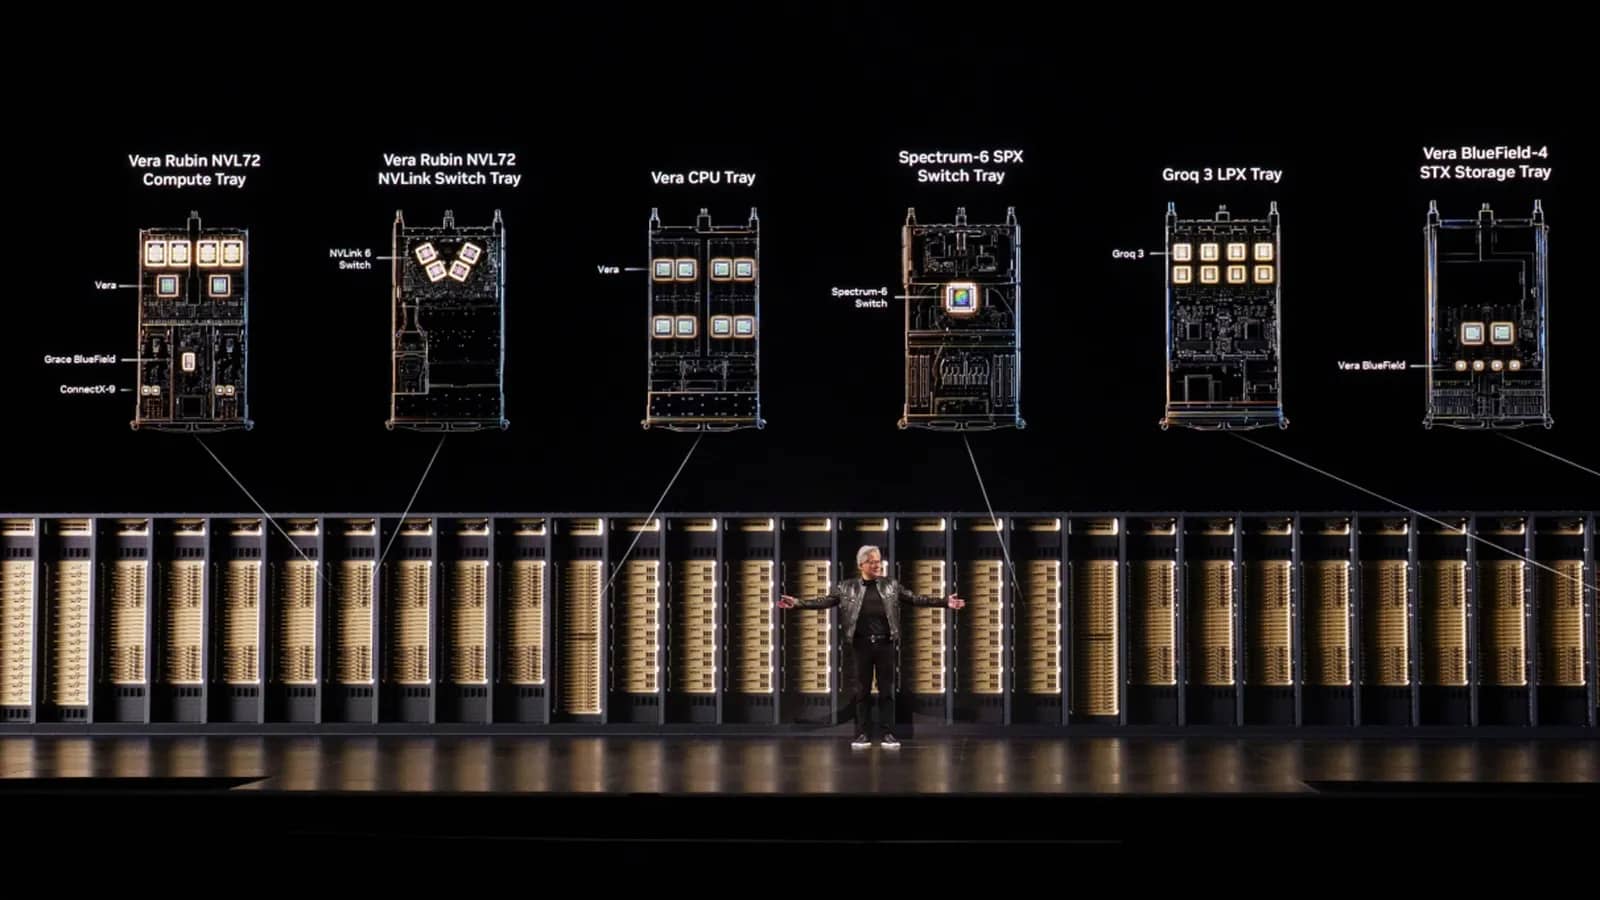
Source:Nvidia
Post
Nvidia says Vera Rubin NVL72 delivers up to 30x GB300 throughput per dollar
Ad
From The CircuitryVerified tech news, cross-checked.How we verify →
Ad
From The CircuitryWhy The Circuitry

Verified tech news, cross-checked.

Every story is checked against independent sources before it posts — no rumors dressed up as fact.

How we verify →
TL;DRAI · 60 sec read

Nvidia said Vera Rubin NVL72 delivers up to 30x the throughput per dollar of GB300 NVL72 at 125 tokens per second per user on one agent workload, while HBM per GPU is up about 3%. A separate comparison puts GB300 NVL72 at up to 10x an H200. The post names no ship date.

Nvidia said on November 5 that Vera Rubin NVL72 delivers up to 30 times the throughput per dollar of GB300 NVL72 on one agent workload, while high-bandwidth memory per GPU is up about 3%. The post names no ship date and no price.
At 125 tokens per second per user, Vera Rubin NVL72 delivers up to 30x higher throughput per dollar than GB300 NVL72, with HBM capacity per GPU up about 3%.
At 125 tokens per second per user, Vera Rubin NVL72 delivers up to 30x higher throughput per dollar than GB300 NVL72, with HBM capacity per GPU up about 3%. Nvidia tied that figure to the SemiAnalysis AgentX DeepSeek V4 Pro workload. A separate line in the same post says GB300 NVL72 delivers up to 10x the throughput per dollar of an H200 platform at 100 tokens per second per user, with HBM capacity per GPU roughly doubling. The two comparisons are not the same jump.
From The CircuitryThe Feed — live briefs across tech, all day.See what’s happening →
The post treats memory pressure as the constraint. Nvidia said frontier models now have trillions of parameters, and that agent trajectories can process up to 3 million tokens in some cases. It said model weights and KV cache compete for HBM, the fastest and most expensive tier. CPU memory, local SSDs, and shared storage sit below it. The post says memory supply is tightening and prices are rising, and that the trend is expected to continue through the near term. It did not give a price index.

The claimed gain is software and placement, not a much larger memory chip. Nvidia said its NVFP4 format reduces the space weights take compared with FP8, which it called the lowest precision possible on Hopper. It said an NVL72 system can spread model weights across up to 72 GPUs, leaving more HBM for cache and concurrent users. It said Dynamo can move inactive context to CMX storage, which is shared across servers and costs less per bit than HBM. It did not state a CMX price or a capacity figure.
Ad
From The CircuitryWhy The Circuitry

Verified tech news, cross-checked.

Every story is checked against independent sources before it posts — no rumors dressed up as fact.

How we verify →
Nvidia also said it was first to adopt HBM3e and HBM4 in an accelerated computing stack. The November 5 post does not say Vera Rubin is shipping, and it does not name a customer or a delivery quarter. The 30x figure is an up-to result on one named workload at one response rate, not a general claim for every model.
Why this mattersAI · ~100 words

Tap a lens to see what this story means for you.

Morning Brief

Liked this? The Brief brings you the whole day in tech, verified, every morning.

Two minutes, free forever. What's in The Brief →

Reader-supported
DonateBuy me a coffee →Follow@thecircuitry_ →Follow@thecircuitry.to →
HELP US IMPROVE
From The Circuitry

See what’s happening right now

The Feed runs all day — short, verified briefs the moment they break.

Open the Feed →
From The Circuitry

Follow @thecircuitry_

Every story we publish, as it happens. No noise between.

Follow on X ↗On Bluesky ↗

Reader-supported

The Circuitry is a passion project I've always wanted to build, and I love the work behind it.

Running it costs real money. APIs, hosting, time. To keep improving the site and growing this into something useful for everyone, those costs have to be covered.

Any contribution is appreciated. If not, no pressure. Thanks for reading.

Buy me a coffee
More inTech
  • FAA ground stop halts departures at U.S. airports

    Tech · 9h
  • Starship Flight 15 reaches orbit after a Gulf splashdown

    Tech · 9h
  • Tesla opens Cybercab orders to select customers at $29,990

    Tech · 9h
SupportThe Work

The Circuitry is reader-supported. If you find the daily brief useful, you can buy me a coffee to keep it going.

Buy a coffee →
Ad
From The CircuitryWhy The Circuitry

Verified tech news, cross-checked.

Every story is checked against independent sources before it posts — no rumors dressed up as fact.

How we verify →
From The CircuitryWhy The Circuitry

Verified tech news, cross-checked.

Every story is checked against independent sources before it posts — no rumors dressed up as fact.

How we verify →

MORE IN THIS BEAT

All Tech →
  • Tech·Nov 13

    DeepSeek opens app tools on the API for V4.1-Flash

    DeepSeek has opened web search, file input, URL reading, and safety checks on the deepseek-flash API. Search, Fetch, OCR, speech recognition, and text-to-speech are also available as standalone calls.

  • Tech·Nov 13

    Starship Flight 15 deploys 26 Starlink satellites in orbit

    Starship has finished deploying all 26 Starlink V3 satellites on Flight 15. SpaceX posted the completion at 8:06 p.m. AST, and at 8:08 p.m. AST said the ship is in a coast intended to last about 21 hours.

  • Tech·Nov 13

    OpenAI opens Daybreak Red Team and Defense Factory

    OpenAI has product pages for Daybreak Red Team and Daybreak Defense Factory. Red Team tests web applications with agents. Defense Factory has agents prepare patches that engineers review before a merge.

  • Tech·Nov 13

    Uber says a vendor breach exposed driver license data

    Uber is notifying drivers that personal and driver's license information was stolen in an October breach at a technology vendor. Uber said the vendor is Fireworks.ai. State notices list thousands of people in three states, and California was notified without a count.

  • Tech·Nov 13

    OpenAI opens ChatGPT Wallet for U.S. Pro users

    OpenAI has introduced ChatGPT Wallet, which lets a dot pay without access to the user's card details. It is starting with ChatGPT Pro subscribers in the United States, and every purchase needs a security check.